AIImpish
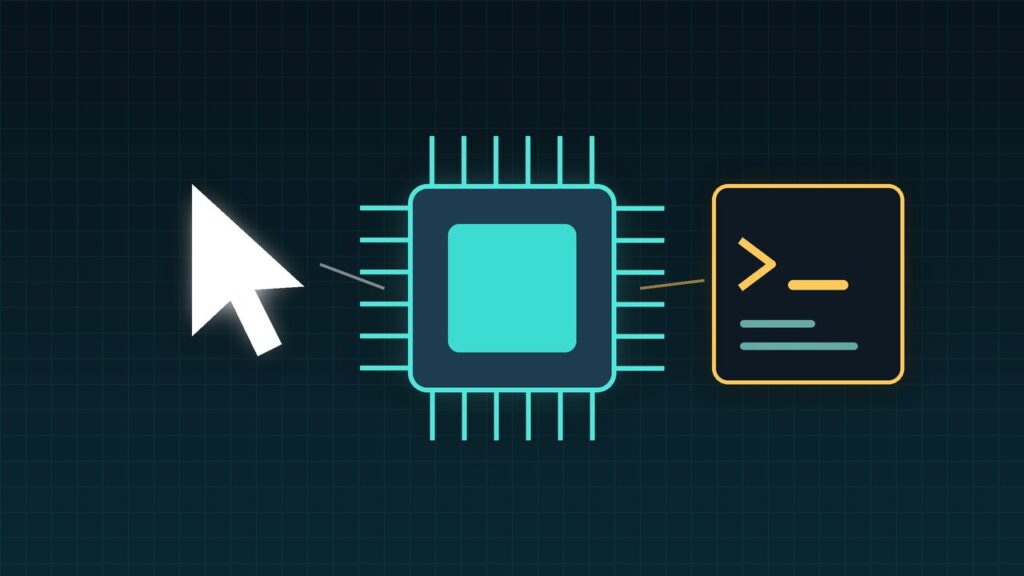
Most computer-use agents work like a person with a mouse: look at a screenshot, click, repeat. Microsoft’s new Mage-VL-Cowork takes a shortcut when it can. The 4-billion-parameter open model can switch between clicking through an app and running code in a terminal, and Microsoft reports 66.0% on the OSWorld-Verified desktop benchmark. The weights went up on Hugging Face on October 30, 2026, under the Apache-2.0 license.
Coffee summary
- FACT: Mage-VL-Cowork is a 4B vision-language model from Microsoft’s Mage team, released under Apache-2.0.
- FACT: It has two action channels:
computer_usefor GUI clicks and typing, andbashfor shell and Python commands. - CLAIM: Microsoft reports 66.0% on OSWorld-Verified (361 tasks, excluding Google Drive, 50-step budget, average of two runs), which it calls the best result at the 4B scale.
- CLAIM: After reinforcement learning, Microsoft says the model uses 13.0% fewer model calls and 25.4% fewer output tokens than its earlier training stage.
- FACT: Microsoft’s model card says to run it only in isolated sandboxes.
What happened
Microsoft published the model, a model card, and an evaluation package on Hugging Face, plus a technical report. The model is built on a Qwen3-4B language backbone with Microsoft’s own Mage-ViT image encoder. It ships as about 9.48 GB of bfloat16 weights and uses a 32,768-token working context.
The key idea is “hybrid” computer use. For visual tasks, like editing an image canvas, the model clicks. For structured edits, like changing a spreadsheet, it writes a short Python script instead of dragging through cells. It makes that choice itself, step by step, without a separate router.
Why it matters
OPINION: Clicking through apps one screenshot at a time is slow for AI agents. For many file tasks, code is faster and easier to verify. A small model that knows when to use each could make desktop agents cheaper to run.
CLAIM: Microsoft’s own demo shows the gap. In a LibreOffice Calc task, Mage-VL-Cowork finished in 39 seconds and 6 steps by editing the file with Python. Qwen3.6-27B, a GUI-only model, took 9 minutes 56 seconds and 39 steps. That is one vendor demo, not a broad benchmark.
How it compares (Microsoft’s numbers)
| Model | OSWorld-Verified (as listed by Microsoft) |
|---|---|
| Human reference | 72.4% |
| GPT-5.4-mini (one run, same 361 tasks) | 69.6% |
| ScaleCUA-Qwen3.5-9B (9B) | 68.7% |
| Mage-VL-Cowork (4B) | 66.0% |
| Qwen3.6-27B (27B) | 63.9% |
| Fara1.5-4B (4B, browser specialist) | 13.9% |
The top proprietary models in the same table (GPT-5.5, Claude Opus 4.7, and GPT-5.4) score higher, from 75.0% to 78.7%. Not every row uses the same step budget or task set, so treat the table as a rough guide.
Who should care
- Developers building desktop agents who want an open, commercially usable model.
- Teams automating office files such as spreadsheets, documents, and slides.
- Researchers interested in the training recipe: Microsoft describes a five-stage curriculum and a synthetic task engine that generated 293,806 tasks.
Limitations
- Self-reported scores. The benchmark numbers come from Microsoft and have not been independently reproduced yet.
- Not plug-and-play. It uses a custom architecture, so you must load it with
trust_remote_code=True, and Microsoft publishes recommended sampling settings and a serving setup. - “On-device” is a goal, not a guarantee. Microsoft says the model pushes on-device intelligence, but 9.48 GB of weights still needs a capable GPU.
- Real risk. A model that runs shell commands can delete files or leak data if misused or tricked by a malicious web page.
What to do next
- Read the model card on Hugging Face before testing, especially the Responsible AI section.
- Sandbox it. Microsoft says to use an isolated container or virtual machine, with no access to host files, local networks, personal environment variables, or credentials.
- Add human approval for irreversible actions such as payments, logins, or sending data out.
- Start with file tasks where results are easy to check, like spreadsheet edits, before trying open-ended web work.
AIImpish Take
Mage-VL-Cowork’s real contribution is the habit it teaches: use code when code is the better tool. If the results hold up independently, small open agents could take on a lot of routine office work at low cost. Builders should test it now, but only inside a locked-down sandbox.
Related on AIImpish
- GPT-6.1 Terra: OpenAI’s Cheaper Model for Computer Use and Everyday Work
- How OpenAI Watches Its Own AI Agents
*Sources: Microsoft, Mage-VL-Cowork model card on Hugging Face; Microsoft Mage project page; Mage-VL-Cowork technical report (PDF).*